Machine learning algorithms power modern digital products, automated software features, and data-driven decision tools across global industries. In 2026, organizations rely on top machine learning algorithms to convert raw data streams into reliable predictions. Software engineers, data science practitioners, and analysts deploy these computational models to solve everyday challenges, ranging from detecting email spam to forecasting quarterly financial revenue.
This educational guide breaks down fundamental learning paradigms, core algorithm mechanics, real-world applications, and practical model selection frameworks to help you build effective AI solutions and outpace competitors.
What Is a Machine Learning Algorithm?
A machine learning algorithm is a mathematical procedure that identifies patterns in data and learns rules to perform tasks without explicit step-by-step programming. Unlike traditional software code relying on human-written conditional rules, a machine learning algorithm accepts input data alongside target outcomes or historical examples. It uses optimization techniques to calculate internal mathematical weights, continuously refining predictions through an automated loss function.
In modern data science algorithms, these models evaluate historical observations, learn underlying relationships across variables, and apply those learned patterns to fresh data. This capability enables automated predictive analytics, adaptive recommendation systems, and the power of machine learning in modern AI solutions.
Quick Guide: Machine Learning at a Glance
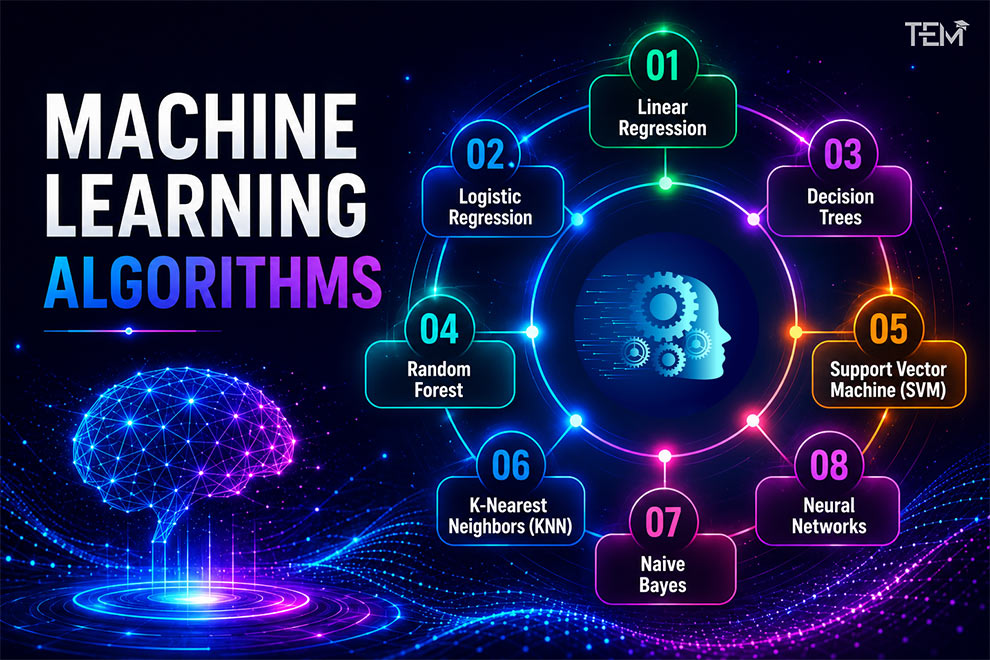
The table below highlights ten representative examples across different learning approaches to help you quickly compare their mechanics and use cases. The detailed sections following this table expand on additional algorithms and specialized deep learning architectures.
| Algorithm or Model | Primary Paradigm | Main Objective | Recommended Data Type | Typical Real-World Use |
| Linear Regression | Supervised | Continuous Prediction | Tabular Continuous | Sales revenue forecasting |
| Logistic Regression | Supervised | Categorical Classification | Tabular Labeled | Credit default risk scoring |
| Decision Trees | Supervised | Classification & Regression | Mixed Tabular | Customer churn prediction |
| Random Forest | Supervised | Ensemble Classification | Large Tabular | Financial fraud detection |
| Support Vector Machines | Supervised | Margin-Based Classification | High-Dimensional | Text and gene categorization |
| K-Nearest Neighbors | Supervised | Instance Classification | Scaled Numerical | Digit recognition |
| K-Means Clustering | Unsupervised | Centroid Grouping | Unlabeled Numerical | Customer market segmentation |
| DBSCAN | Unsupervised | Density Grouping | Spatial Geographic | Traffic anomaly mapping |
| Principal Component Analysis | Unsupervised | Dimensionality Reduction | High-Dimensional | Feature compression and prep |
| Convolutional Neural Networks | Deep Learning | Spatial Pattern Analysis | Multi-Channel Images | Medical imaging diagnostics |
Learning Paradigms vs. Specific Algorithms
A fundamental concept in machine intelligence is the distinction between overarching learning paradigms, specific data science algorithms, and deep learning architectures. A learning paradigm defines the training environment and data structure, while an algorithm provides the mathematical procedure that extracts patterns within that environment.
Supervised Learning
Supervised learning trains models on labeled datasets containing input features paired with known ground-truth targets. The algorithm measures prediction errors against target labels, adjusting parameters through cross-validation to manage the bias-variance tradeoff and prevent overfitting. Supervised models excel at numerical regression and categorical classification on structured tables.
Unsupervised Learning
Unsupervised learning operates on unlabeled data without target labels. The algorithm analyzes feature distributions to discover natural groupings, hidden associations, or simplified lower-dimensional representations. Unsupervised models form the backbone of exploratory data analysis, market segmentation, and anomaly detection.
Semi-Supervised Learning
Semi-supervised learning addresses scenarios where obtaining fully labeled data is expensive or time-consuming. This hybrid paradigm combines a small set of labeled samples with a large pool of unlabeled data. The system uses labeled instances to establish initial decision boundaries while leveraging unlabeled instances to capture broader data distributions.
Reinforcement Learning
Reinforcement learning focuses on dynamic decision-making through trial-and-error interaction with an environment. An autonomous agent observes environmental states, executes actions, and receives numerical feedback as rewards or penalties. Through hyperparameter tuning and policy optimization, the agent learns to maximize cumulative rewards, powering autonomous vehicles, robotics, and game AI.
Top Supervised Machine Learning Algorithms
Supervised methods form the primary engine of commercial predictive analytics because they map input data directly to actionable target outcomes.
1. Linear Regression
- What It Is: Linear regression is a supervised algorithm predicting continuous numerical values based on linear relationships between variables.
- How It Works: It calculates slope coefficients defining a trendline that minimizes squared prediction errors across data points.
- When To Use It: Use linear regression for straightforward numerical predictions, such as quarterly sales forecasting. It offers fast computation and simple coefficient interpretation, though it struggles with non-linear trends and statistical outliers.
2. Logistic Regression
- What It Is: Logistic regression is a classification algorithm predicting categorical outcomes, such as binary pass or fail status.
- How It Works: It transforms linear input combinations through a sigmoid activation function, outputting probability values between zero and one.
- When To Use It: Use logistic regression for binary decision tasks like credit default evaluation and email spam filtering. Note that its decision boundary is linear in the supplied feature space unless you explicitly create non-linear feature transformations.
3. Decision Trees
- What It Is: A decision tree is a flowchart-like model that splits data into smaller subsets to solve classification and regression problems.
- How It Works: The algorithm evaluates features at each node using mathematical split criteria such as Gini impurity or Information Gain to maximize target class purity.
- When To Use It: Use decision trees when stakeholders require transparent decision logic, such as loan approval scoring. Decision trees handle mixed data types without requiring feature scaling, though unconstrained trees easily overfit noisy training data.
4. Random Forest
- What It Is: Random Forest is an ensemble machine learning algorithm that trains multiple decision trees on different samples of data and features. It combines their predictions to improve model stability and reduce individual tree overfitting.
- How It Works: During training, each tree samples a random subset of rows and features using bootstrap aggregation. The ensemble outputs the majority vote for classification or the mathematical average for regression.
- When To Use It: Use Random Forest for complex tabular datasets like stock volatility estimation and fraud detection. Note that whether missing values can be handled natively depends on the specific software library and estimator version, so explicit feature imputation remains common practice in data science workflows.
5. Support Vector Machines (SVM)
- What It Is: Support Vector Machines find optimal decision boundaries that maximize the margin between distinct data categories.
- How It Works: SVM calculates a hyperplane separating classes. For non-linear data, it uses kernel functions to project features into higher-dimensional spaces where linear separation becomes possible.
- When To Use It: Use SVM for high-dimensional classification tasks such as text categorization or gene expression analysis. It remains memory efficient by relying on boundary support vectors, though training can be slow on large datasets.
6. K-Nearest Neighbors (KNN)
- What It Is: K-Nearest Neighbors is an instance-based algorithm that classifies new data points based on their similarity to stored training examples.
- How It Works: When classifying a new point, KNN measures distance metrics, such as Euclidean distance, to locate its K closest neighbors and assigns the majority label among them.
- When To Use It: Use KNN for tasks like handwriting digit classification or grouping new customers near similar historical profiles. Feature scaling is generally important when input features use different measurement units, and inference can be computationally expensive on large datasets.
Top Unsupervised Machine Learning Algorithms
Unsupervised algorithms discover hidden structures in unorganized data, powering self-directed discovery and automated data prep.
1. K-Means Clustering
- What It Is: K-Means is a centroid-based clustering algorithm dividing unlabeled data into K distinct groups.
- How It Works: The algorithm selects K initial centroid points, assigns each point to its nearest centroid, and recalculates centroid positions by taking the mean of assigned points. This process repeats until a specified stopping criterion, such as convergence tolerance or maximum iteration limit, is reached.
- When To Use It: Use K-Means for market segmentation and customer persona creation. It scales cleanly to large datasets, but you must specify K in advance, and it struggles with irregular cluster shapes.
2. DBSCAN
- What It Is: Density-Based Spatial Clustering of Applications with Noise (DBSCAN) groups data points based on spatial density thresholds.
- How It Works: It measures spatial density parameters, expanding clusters through dense neighborhoods while marking isolated points in sparse regions as noise or outliers.
- When To Use It: Use DBSCAN for urban traffic mapping and spatial anomaly detection. It automatically identifies arbitrary cluster shapes and isolates statistical noise without requiring a preset cluster count.
3. Principal Component Analysis (PCA)
- What It Is: PCA is an unsupervised dimensionality reduction technique that condenses large feature sets while preserving essential variance.
- How It Works: It calculates linear combinations of correlated features, projecting the original dataset onto a smaller set of uncorrelated axes called principal components.
- When To Use It: Use PCA during preprocessing to remove feature redundancy and accelerate downstream model training, though transformed components obscure direct feature meaning.
Deep Learning Models and Neural Networks
Deep learning represents a specialized subfield of machine intelligence inspired by biological brain structures. Stacked layers of artificial neural networks learn complex feature representations directly from raw inputs.
- Artificial Neural Networks (ANN): Artificial Neural Networks consist of input, hidden, and output layers. Interconnected nodes pass signals forward using weights and activation functions, adjusting parameters during backpropagation to learn non-linear patterns on tabular data and numeric functions.
- Convolutional Neural Networks (CNN): Convolutional Neural Networks sweep mathematical filters across grid data like images to detect hierarchical visual patterns. Deep learning models are often highly effective for complex, high-dimensional unstructured visual data. However, traditional machine learning algorithms can also process images when paired with explicit feature extraction techniques like edge detection or histogram of oriented gradients. Transfer learning with pre-trained CNN architectures allows effective fine-tuning on smaller datasets.
- Recurrent Neural Networks (RNN): Recurrent Neural Networks feature internal memory loops that pass information across sequence steps. This architectural design enables RNNs and Long Short-Term Memory variants to process temporal data like speech recognition and time-series telemetry.
- Transformer Architectures: Transformers use self-attention mechanisms to evaluate contextual relationships across an entire input sequence simultaneously. While Transformers power modern Large Language Models and multimodal generative AI, they represent specialized deep learning architectures rather than universal replacements for traditional tabular machine learning algorithms.
How Machine Learning Algorithms Power Modern AI Systems (Real-world Applications)
The surge in AI capability over the last few years is directly linked to the evolution of these algorithms. Modern AI systems like Large Language Models (LLMs) and generative AI rely on deep learning models, which are advanced versions of these neural networks.
- Generative AI: Algorithms like Transformers allow models to understand the context of language and generate human-like text or images.
In 2026, companies like Volkswagen and Mercedes-Benz have integrated Gemini models into their “Smart Cockpits.” Drivers can point their smartphone camera at a dashboard warning light (Computer Vision), and the generative AI will explain what it means in plain language and even schedule a service appointment autonomously.
- Computer Vision: Convolutional Neural Networks (CNNs) enable autonomous vehicles to “see” and navigate roads safely.
NVIDIA’s latest automotive platform is currently powering a new generation of Levelhttps://nvidianews.nvidia.com/news/drive-hyperion-level-4, Nissan, and Hyundai. Using CNN-based perception, these vehicles can distinguish between a child standing on a curb and a cardboard cutout, even in heavy rain or low-light conditions.
- Recommendation Systems: Algorithms analyze your past behavior to suggest products or content you are likely to enjoy.
By 2026, Spotify doesn’t just recommend songs based on genre; it uses context signals (like the time of day, your current location, and even your movement speed) to adjust your playlist in real-time. Similarly, Amazon uses predictive analytics to move products to local distribution centers before a customer in that area officially places an order, based on the high probability of purchase predicted by their deep learning models.
How to Choose the Right Machine Learning Algorithm
Selecting an appropriate algorithm requires evaluating your data characteristics, interpretability needs, and resource constraints through a four-step framework:
- Identify Your Target Variable: Choose supervised learning algorithms for labeled target outcomes, and unsupervised learning algorithms for unlabeled datasets.
- Examine Data Structure and Volume: Structured tabular data with thousands of rows pairs well with Random Forest or Logistic Regression. Unstructured visual or text data often benefits from deep learning models.
- Assess Interpretability Requirements: Interpretability obligations vary across jurisdictions and operational use cases. When transparent logic is important, such as evaluating credit applications, Linear Regression or Decision Trees offer clear advantages over black-box models.
- Benchmark Resource Constraints: Evaluate training duration, memory footprint, hyperparameter tuning complexity, and real-time inference latency before deploying models to production environments.
Industry Insights and Future Trends
The field of machine learning continues to evolve rapidly. Exploring future trends and predictions in machine learning reveals how research moves toward higher data efficiency and physical world interaction. You can also view our analysis on emerging AI trends for 2026.
During his March 2017 address at the Stanford Graduate School of Business (“Artificial Intelligence is the New Electricity”), AI pioneer Dr. Andrew Ng highlighted the transformative reach of these technologies: “AI is the new electricity. Just as electricity transformed almost everything 100 years ago, today I actually have a hard time thinking of an industry that AI will not transform.”
Addressing structural boundaries in current AI paradigms, computer scientist Dr. Yann LeCun discussed the limitations of purely text-based training in his 2024 essay AI And The Limits Of Language (published in Noema Magazine). He noted that human-level intelligence requires learning from physical world interaction, visual input, and sensory perception rather than linguistic training data alone.
Reflecting on changing human-computer interaction during his Microsoft Ignite 2023 keynote address, Microsoft CEO Satya Nadella observed: “The fundamental breakthrough is that we are moving from a world where we had to understand computers to a world where computers understand us.”
Key developments shaping 2026 include:
- Edge AI Deployment: Executing lightweight algorithms directly on local hardware to minimize latency and protect data privacy.
- Explainable AI (XAI): Implementing model auditing tools to interpret complex predictions in regulated enterprise workflows.
- Hybrid Workflows: Combining traditional tabular predictive analytics with generative AI to build autonomous agent systems.
Conclusion
Understanding top machine learning algorithms is essential for building effective AI solutions in 2026. By matching supervised learning for targeted predictions, unsupervised learning for automated discovery, and deep learning models for complex unstructured inputs, enterprise teams establish reliable predictive capabilities.
Successful implementation relies on selecting the right data science algorithms for your specific dataset, interpretability demands, and performance targets. Matching your operational goals to these core machine learning models ensures that your AI automation projects deliver long-term value and competitive advantage.
FAQ
What are the main learning paradigms in machine learning?
The four main paradigms are supervised learning, unsupervised learning, semi-supervised learning, and reinforcement learning. Supervised learning uses labeled target data, unsupervised learning extracts patterns from unlabeled data, semi-supervised learning combines both, and reinforcement learning optimizes decisions through environmental rewards.
How do K-Means and KNN differ in practice?
K-Means is an unsupervised clustering algorithm that groups unlabeled data around calculated centroid points. K-Nearest Neighbors (KNN) is a supervised classification and regression algorithm that assigns labels to new data points based on the majority class of surrounding training instances.
Do traditional ML algorithms require manual feature engineering?
Manual feature engineering is common in many traditional machine learning workflows to boost model performance, but it is not a universal requirement for every baseline model or tabular algorithm.
Why choose Random Forest over a single Decision Tree?
A single decision tree often overfits training data and exhibits high variance. Random Forest builds an ensemble of diverse trees trained on random data subsets and combines their predictions, yielding far greater stability and generalization accuracy.